Unified Framework for Heterogeneous AI Accelerators: Testing Whether AI Inference Frameworks Can Cross the GPU Vendor Divide
Modern AI infrastructure is deeply shaped by the GPU ecosystem. NVIDIA and CUDA have become the dominant standard for many AI workloads, but the future of AI compute may depend on more heterogeneous systems that can work across different hardware vendors.
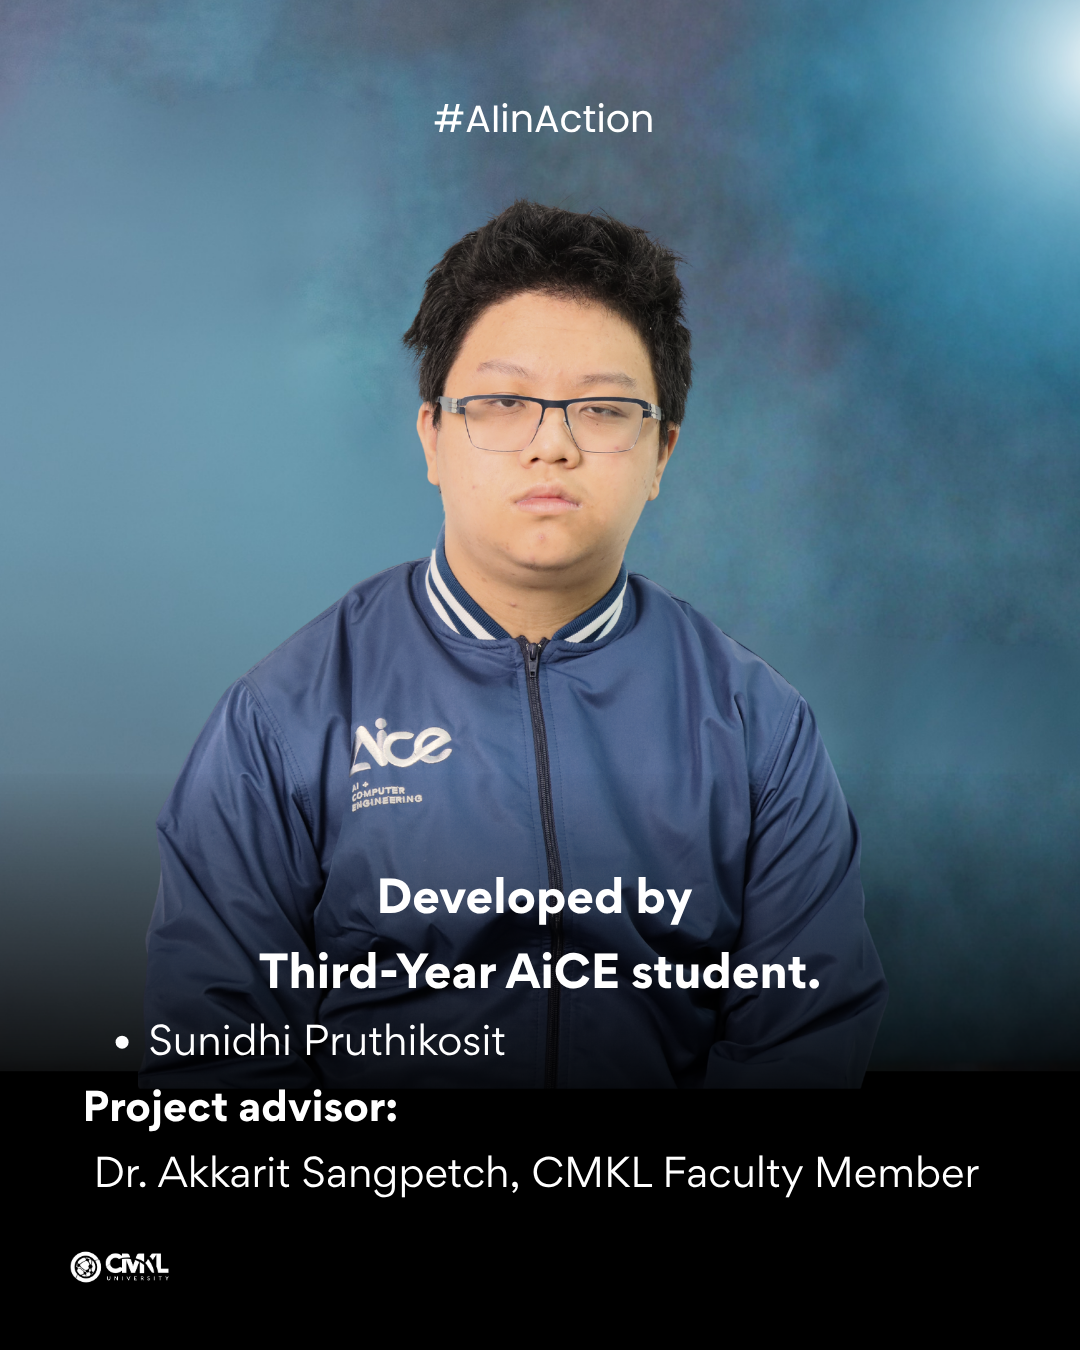
This project, developed by AiCE 3rd year student Sunidhi Pruthikosit under the guidance of Dr. Akkarit Sangpetch, investigates whether NVIDIA’s Dynamo inference framework can be adapted to run with AMD/ROCm workers. The project explores an advanced systems question: can AI inference frameworks designed around one vendor’s ecosystem be modified to support competing hardware?
NVIDIA Dynamo is designed as an inference orchestration framework for large-scale AI serving. It can manage worker nodes, support KV cache routing, and coordinate inference engines. However, parts of the ecosystem depend heavily on NVIDIA-specific libraries, especially NIXL for inference transfer.
The project tested whether the engine-agnostic architecture of Dynamo could be extended by replacing CUDA-based inference components with ROCm-compatible alternatives. The work involved experimenting with ROCm-compatible vLLM, modifying dependency assumptions around NIXL, and exploring RIXL as AMD’s reimplementation of the inference transfer library.
To make the system work, the project pinned compatible versions of ROCm, PyTorch, NVIDIA Dynamo, vLLM, RIXL, and UCX, then packaged the stack into Docker for transfer and benchmarking. The project was able to demonstrate that AMD workers can run in a modified Dynamo-based system, providing a proof of concept for cross-vendor experimentation.
However, the benchmark results showed that performance on AMD MI210 hardware remained significantly behind the NVIDIA A100 setup. The project also found that cross-vendor disaggregated serving remains difficult due to transfer-library and UCX compatibility issues.
The value of the project lies not only in performance outcomes, but in the technical exploration itself. It identifies where hardware interoperability breaks down and where future systems research may be needed. As AI models become larger and inference demand grows, questions of vendor lock-in, portability, and heterogeneous compute will become increasingly important.
This project shows CMKL students engaging with the infrastructure layer of AI, where progress depends on deep understanding of systems, hardware, libraries, and performance trade-offs.
Project Member: Sunidhi Pruthikosit
Advisor: Dr. Akkarit Sangpetch
Domain: AI Infrastructure, GPU Systems, Heterogeneous Computing, LLM Inference, ROCm, NVIDIA Dynamo


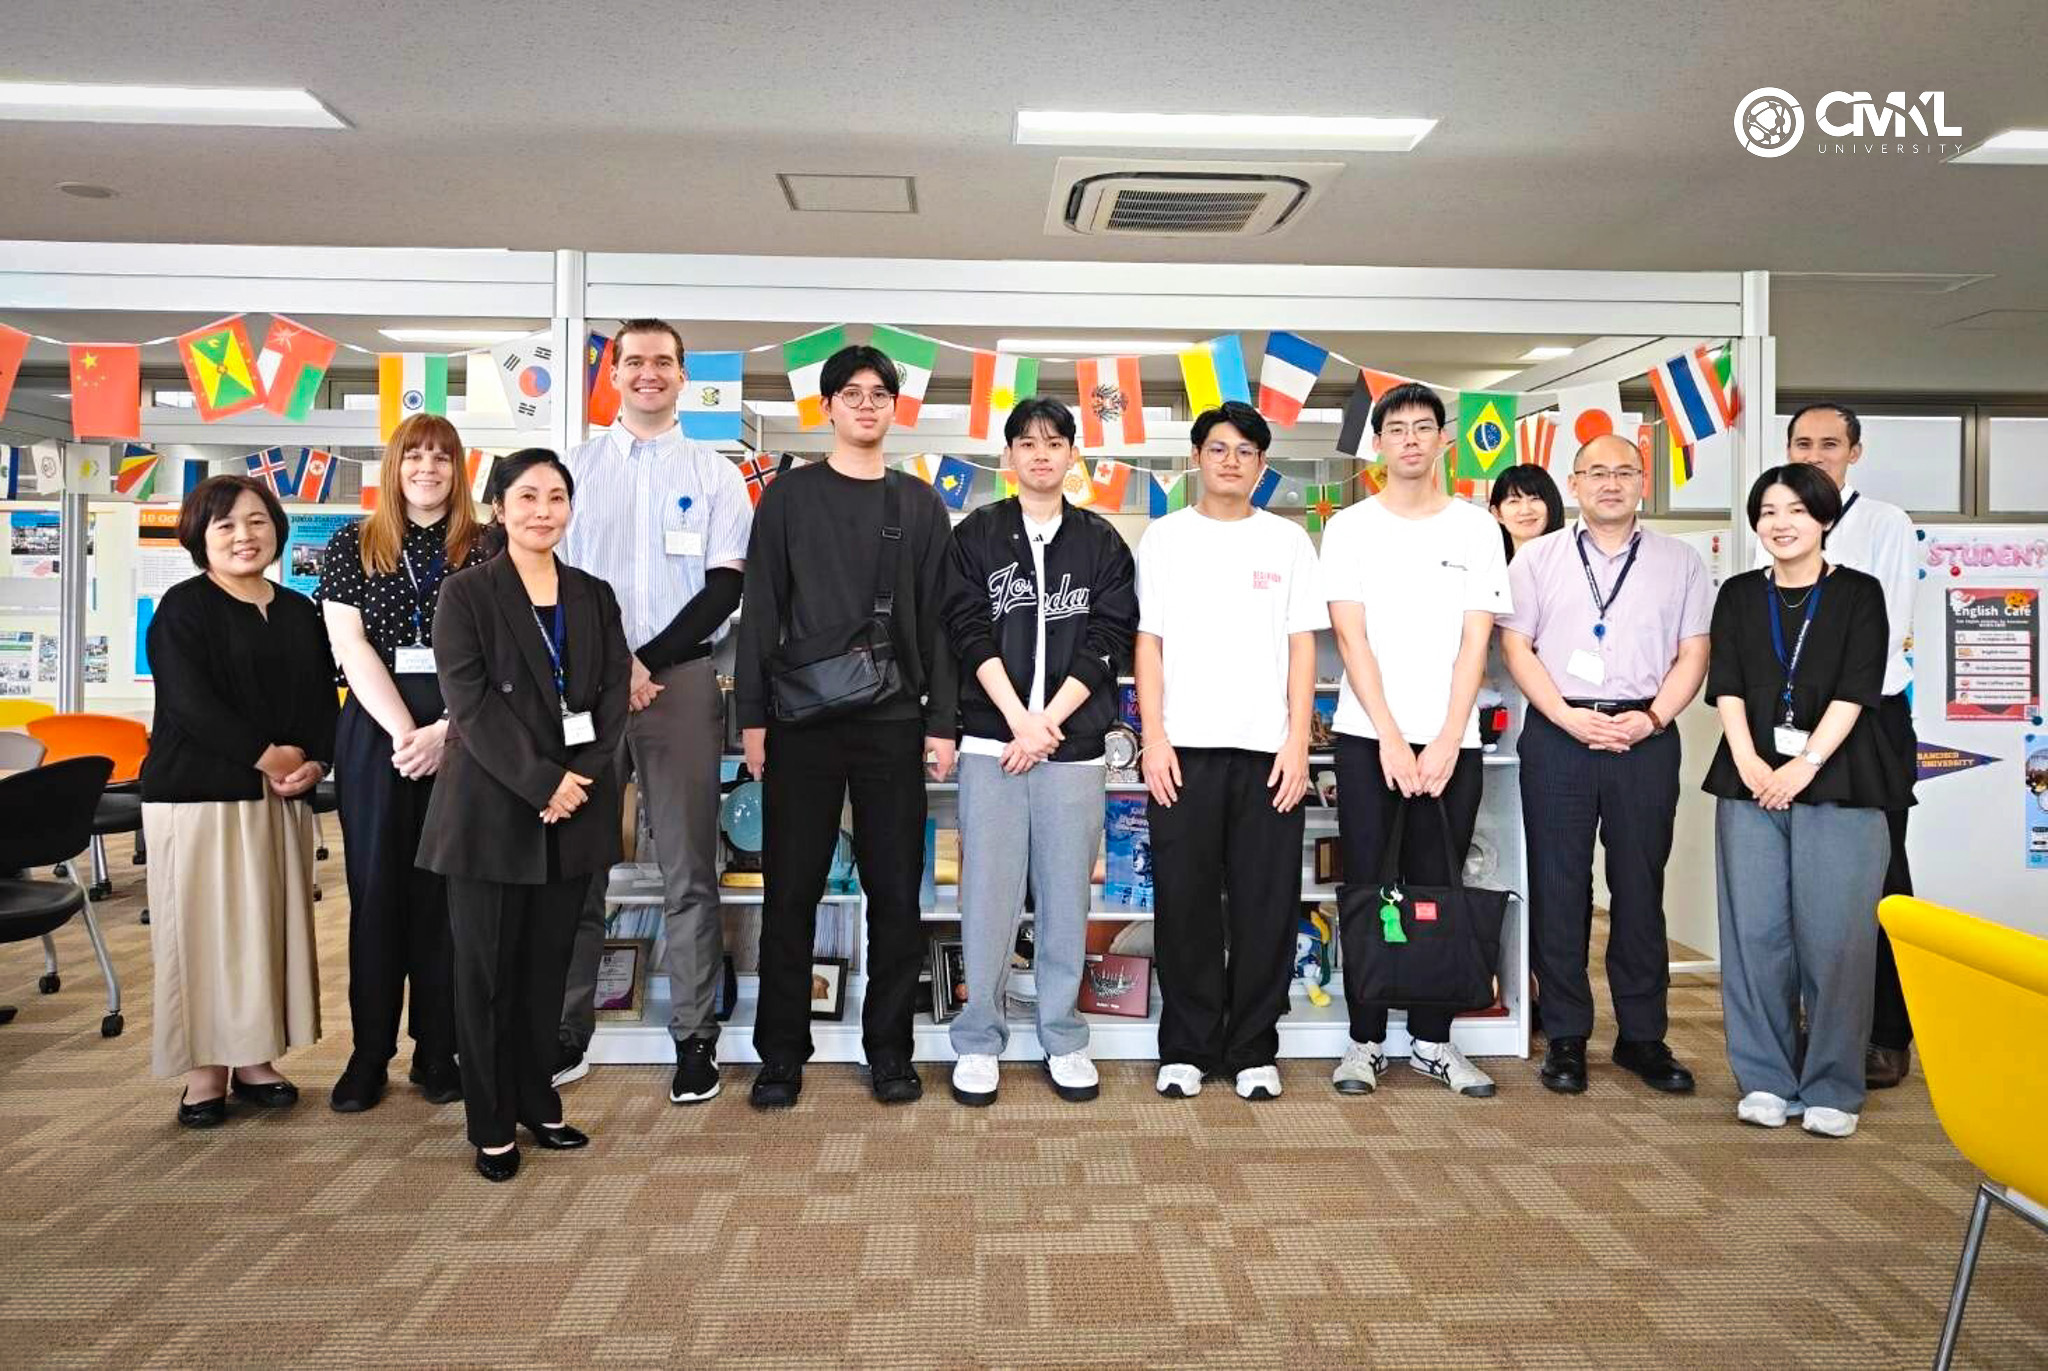
Four Artificial Intelligence and Computer Engineering students will spend nearly three months at Fukuoka Institute of Technology, expanding their research experience through CMKL’s academic collaboration in Japan.
Read more
CMKL University hosted the online AI Innovator Award 2026 Competition Orientation, welcoming young innovators from Thailand, the Philippines, the United Kingdom, the United States, and beyond as they begin their competition journey.
Read more
New monthly series brings CMKL faculty and the public together to examine how artificial intelligence can move from promising technology to responsible, practical adoption.
Read more